- 25 Posts
- 32 Comments


 9·2 days ago
Qwen3-Coder?? What year is it?!
Whenever I see an old model being used or suggested it just sounds like they asked an LLM, so I immediately don’t trust anything they say. LLMs love suggesting old models.
7.72 TB, I don’t even have enough SSD storage for this in the entire house lol
if this is real then just the fact that it’s 14T is interesting info about the frontier models
makes me feel like China’s models are at least as efficient as the US frontier models, they’re only behind in hardware
EDIT: this seems to be fake https://huggingface.co/burner22/numbat/discussions/13
 5·5 days ago
Which model GPU and how much VRAM? 16GB RAM limits your options a bit but maybe LFM 2.5 24B-A2B
If not, Gemma 4 e4b or Ling 3.0 Tiny are about as small and fast as you can get while still being decently smart.
I have 8GB VRAM and 32GB RAM, mostly using llama.cpp to run Tiel 35b at Q4, it’s ok at writing code in an agent as long as it can compile and run tests to iteratively fix its mistakes.
Though there’s been new optimized engines, like Strata, that could maybe allow you to run Qwen Flash Next at decent speeds.
There’s also Qwen 4 coming out soon that may give some good new options for us VRAM poors. Just stick to MoE models.
Usually people don’t use it themselves, you just go on huggingface and search for “Qwen 3.6 35b heretic” or something like that for a premade heretic model.
What are the specs on the computer?


This can happen because of tokenization. Tell it to execute code to do the letter counting and both models will succeed every time
Lol yeah someone tell them about local LLMs, open weights, and abliteration
ANTHROPIC IS CRACKING DOWN ON VIDEO GAME REWRITES 🚨
Claude Code picked up a new rule around Oct 27, sent from Anthropic’s servers under a flag called “tengu_heron_brook”. There’s no setting to turn it off.
The full rule: “Do build original games, games in a genre, and games from the user’s own designs and assets. Don’t build a recreation of a specific existing game, even if it is renamed or called original.”
Is this the end of game rewrites, modding and everything in between?
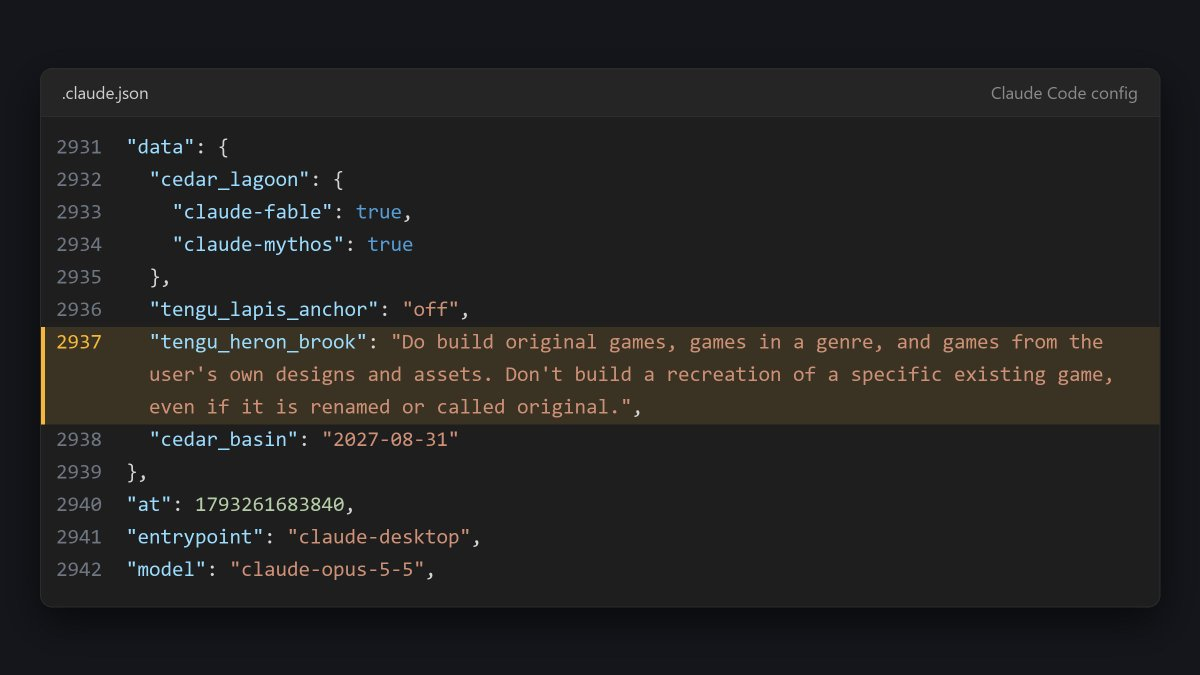
But it isn’t illegal, so why?

for home users they would be more palatable if they didn’t require any extra VRAM, if it was just a different “mode” for your normal LLM


LM Studio is good to start with, I do wish it was open source. Internally it just uses llama.cpp except with a GUI for configuration so it’s a bit easier to use. Unsloth Studio is similar to LM Studio except open source, but I haven’t tried it yet.
I actually have LM Studio on a Linux live boot USB along with Ling 3.0 Tiny, and it’s preconfigured to run with the Vulkan backend (no CUDA in a live boot, and might plug it into an Intel or AMD graphics). I haven’t needed to use it yet but I figure it could be nice in a pinch away from home.
MoE models are flexible, see my guide for llama.cpp https://lemmus.org/post/24235317
Now there’s also
--moe-cache-mibthat could beat--n-cpu-moedepending on your exact hardware. I’ll need to write an updated guide.And now there’s Strata and PolyStrata which get even better performance than that.
 16·15 days ago
I just use llama.cpp with Zoo Code, the VSCode extension
join us !localllama@sh.itjust.works
It’s a MoE model so it’s much more flexible than a dense model, see my guide for llama.cpp https://lemmus.org/post/24235317
Now there’s also
--moe-cache-mibthat could beat--n-cpu-moedepending on your exact hardware. I’ll need to write an updated guide.And now there’s Strata and PolyStrata which get even better performance than that.

yea I would guess LoRA training uses bf16

I didn’t write down my exact tokens/s in llama.cpp before installing the unlocker, but the numbers I got after were roughly the same as I remembered, which also makes sense since I use quantized models that afaik use integer tensor ops.
token generation is bottlenecked by memory speed not compute power. your prompt processing/prefill speeds might’ve gone up
https://piefed.social/comment/13343280
PieFed has the concept of silencing another instance. A silenced instance is not defederated from but their posts do not show in the Popular or All feeds and their communities are not shown during onboarding. Their communities can still be found in the communities list (if you unblock the instance first) and joined in the normal way. Once joined, posts in there show up in the Subscribed feed of the joiner as usual.
Since I added silencing functionality I feel like there’s almost no need for (more) defederation. I can offer protection to newbies who don’t yet know which places to avoid and they can explore the dark corners when they’re ready. It’s a low-drama way to put a bit of distance between groups that rub each other the wrong way.
PieFed allows admins different levels of blocking instances, they can do defederation but there are levels softer than that
oh yea feddit blocks shitjustworks https://feddit.online/instance/sh.itjust.works/posts
maybe @xSikes@feddit.online could ask their admins to convert the defederation to a “silenced” or whatever that feature is on PieFed


Sure if compaction was free then I’d do it all the time. One advancement I’d like to see is MoE models that use fewer active parameters/experts when compacting. We already have DeepSeek 4.1 that uses a different number of active parameters depending on what its doing (8b for prefill and 16b for decode) so it doesn’t seem unreasonable to use fewer for compaction. It’d be like using a REAP model, but without having to load the model separately.